Qwen parent
Loading
Qwen Open / 27B
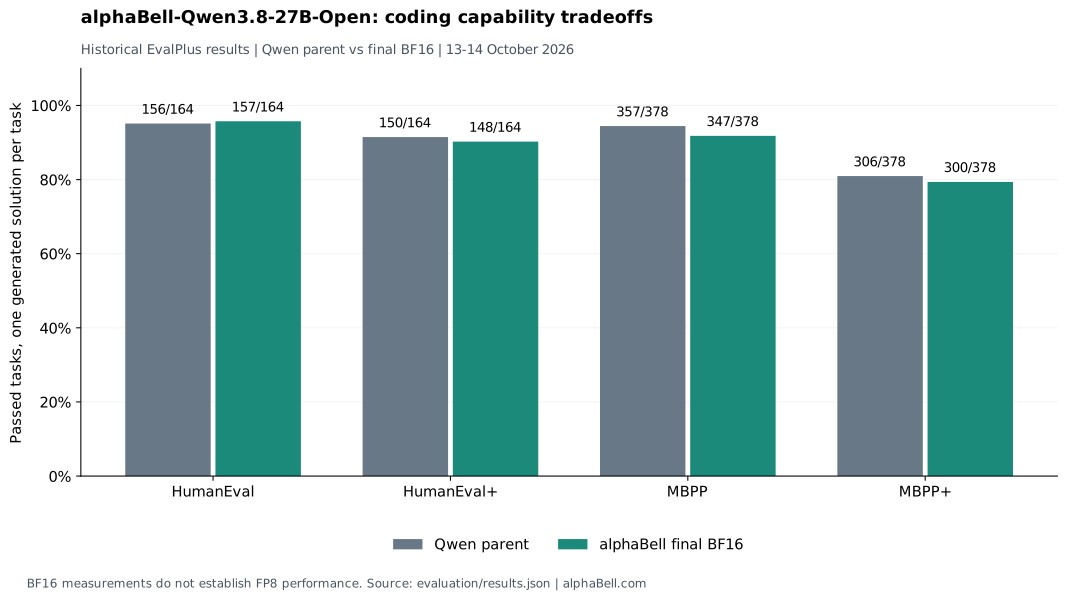
Compare the Qwen parent with alphaBell's final BF16 checkpoint on HumanEval and MBPP. Explore the original tests, the extended tests, and the tasks whose outcomes changed.
Qwen parent
Loading
alphaBell final BF16
Loading
Change
Loading
These are recorded BF16 scores. Complete FP8 benchmark parity remains untested. More answers do not establish better task performance.
Loading evaluation records
Download results JSON ↓| Task | Qwen parent | alphaBell BF16 | Outcome |
|---|
No tasks match these filters.
Evaluation records could not load. Reload this page to try again.
Recorded CPU check
“Reply with one short sentence: hello, and what is 2 + 3?”
Hello, 2 + 3 is 5.
Recorded BF16 CPU output, 12 tokens, thinking disabled. This explorer does not run a chat model.
Original and extended tests score the same generated solution. An improvement means the final BF16 model passed a task the parent failed; a regression means the reverse. Unchanged tasks can be passes or failures for both models.
The runs used a maximum of 16,384 generated tokens with EvalPlus sanitization and scoring. Two final HumanEval generations reached the token limit; MBPP had none. The model combines abliteration and supervised fine-tuning. Its training includes Alpaca replay data, and the derivative is for noncommercial research.